Build a codebase index for RAG with CocoIndex. CocoIndex provides built-in support for codebase chunking, with native Tree-sitter support and real-time updates.
Because CocoIndex uses incremental processing, an update re-processes only the changed files. With a source that pushes change notifications, such as a code editor, the index can follow edits as they happen. Use the index for code search or to retrieve context for AI code generation.
Browse the CocoIndex source on GitHub.
Tree-sitter
CocoIndex uses Tree-sitter to chunk code along its syntax structure rather than at arbitrary line breaks. Chunks that follow the syntax give retrieval whole functions and blocks to return, instead of fragments.
Tree-sitter is a parser generator tool and an incremental parsing library; it is available in Rust.
An updated V0 version of this project is in examples/code_embedding on the v0 branch; it detects the language with the built-in DetectProgrammingLanguage and adds a query handler.
The indexing path is about 50 lines of Python.
Use case
A codebase index gives semantic context to:
- AI coding agents such as Claude, Codex and Gemini CLI, and MCP servers for editors such as Cursor, Windsurf and VS Code.
- Code search by natural language.
- Code generation, autocompletion and assistant bots.
- Code review: automated analysis, quality checks and pull request summaries.
- Refactoring and large-scale code migration.
Why build with CocoIndex?
- The core engine runs in Rust.
- Incremental processing re-processes only what changed, so a change does not re-index the whole codebase.
- The logic is yours to change: the embedding model, the chunking and the vector database.
Prerequisites
If you don’t have Postgres installed, follow the installation guide. CocoIndex uses Postgres to keep track of data lineage for incremental processing.
Define indexing flow
Flow design
The flow:
- Read code files from the local filesystem
- Extract file extensions, to get the language of the code for Tree-sitter to parse
- Split code into semantic chunks using Tree-sitter
- Generate embeddings for each chunk
- Store in a vector database for retrieval
1. Add the codebase as a source
@cocoindex.flow_def(name="CodeEmbedding")
def code_embedding_flow(flow_builder: cocoindex.FlowBuilder, data_scope: cocoindex.DataScope):
    """
    Define an example flow that embeds files into a vector database.
    """
    data_scope["files"] = flow_builder.add_source(
        cocoindex.sources.LocalFile(path="../..",
                                    included_patterns=["*.py", "*.rs", "*.toml", "*.md", "*.mdx"],
                                    excluded_patterns=[".*", "target", "**/node_modules"]))
    code_embeddings = data_scope.add_collector()
We ingest the CocoIndex codebase from the root directory. Change path to the codebase you want to index.
It indexes files ending in .py, .rs, .toml, .md and .mdx. It skips hidden files and directories at the root (.*), target at the root, and node_modules at any depth. To skip hidden directories at any depth, as the V0 example does, use **/.*.
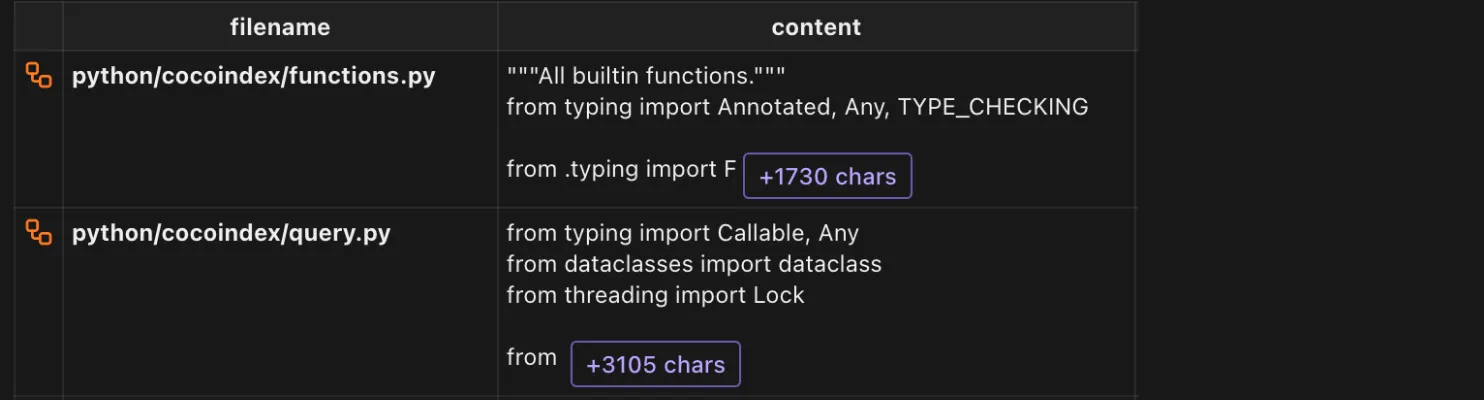
flow_builder.add_source will create a table with sub fields (filename, content). We can refer to the documentation for more details.
2. Process each file and collect the information
2.1 Extract the extension of a filename
We need to pass the language (or extension) to Tree-sitter to parse the code. Let’s define a function to extract the extension of a filename while processing each file. See the custom functions documentation.
@cocoindex.op.function()
def extract_extension(filename: str) -> str:
    """Extract the extension of a filename."""
    return os.path.splitext(filename)[1]
Then process each file and collect the information.
with data_scope["files"].row() as file:
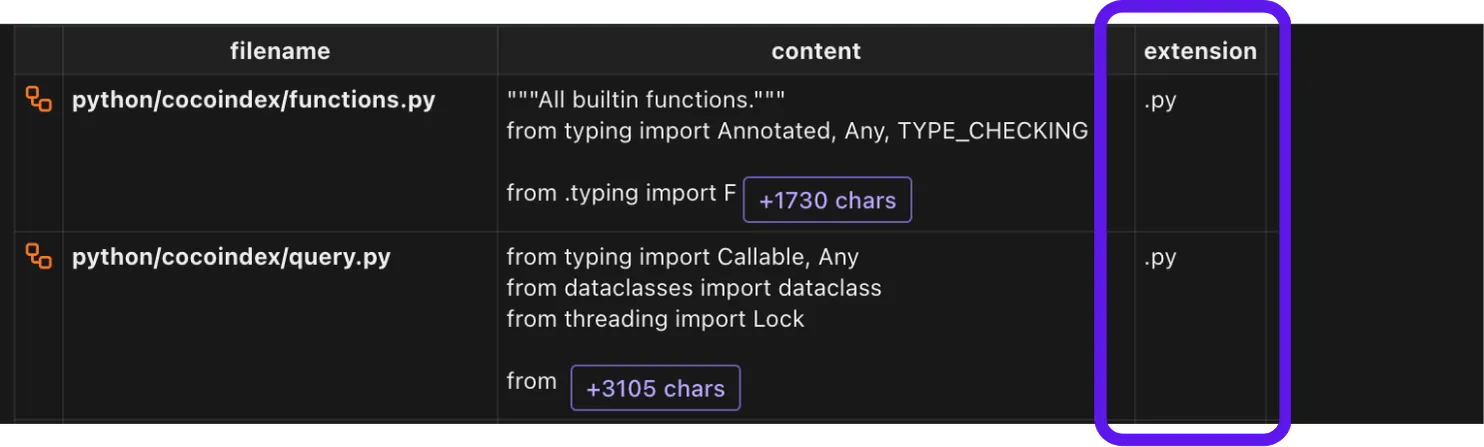
    file["extension"] = file["filename"].transform(extract_extension)
Here we extract the extension of the filename and store it in the extension field.
2.2 Split the file into chunks
We will chunk the code with Tree-sitter.
We use the SplitRecursively function to split the file into chunks.
It is integrated with Tree-sitter, so you can pass in the language to the language parameter.
Supported languages include Python, Rust, JavaScript, TypeScript, Java and C++; the functions documentation lists all language names and extensions. If it’s unspecified or the specified language is not supported, it will be treated as plain text.
with data_scope["files"].row() as file:
    file["chunks"] = file["content"].transform(
          cocoindex.functions.SplitRecursively(),
          language=file["extension"], chunk_size=1000, chunk_overlap=300)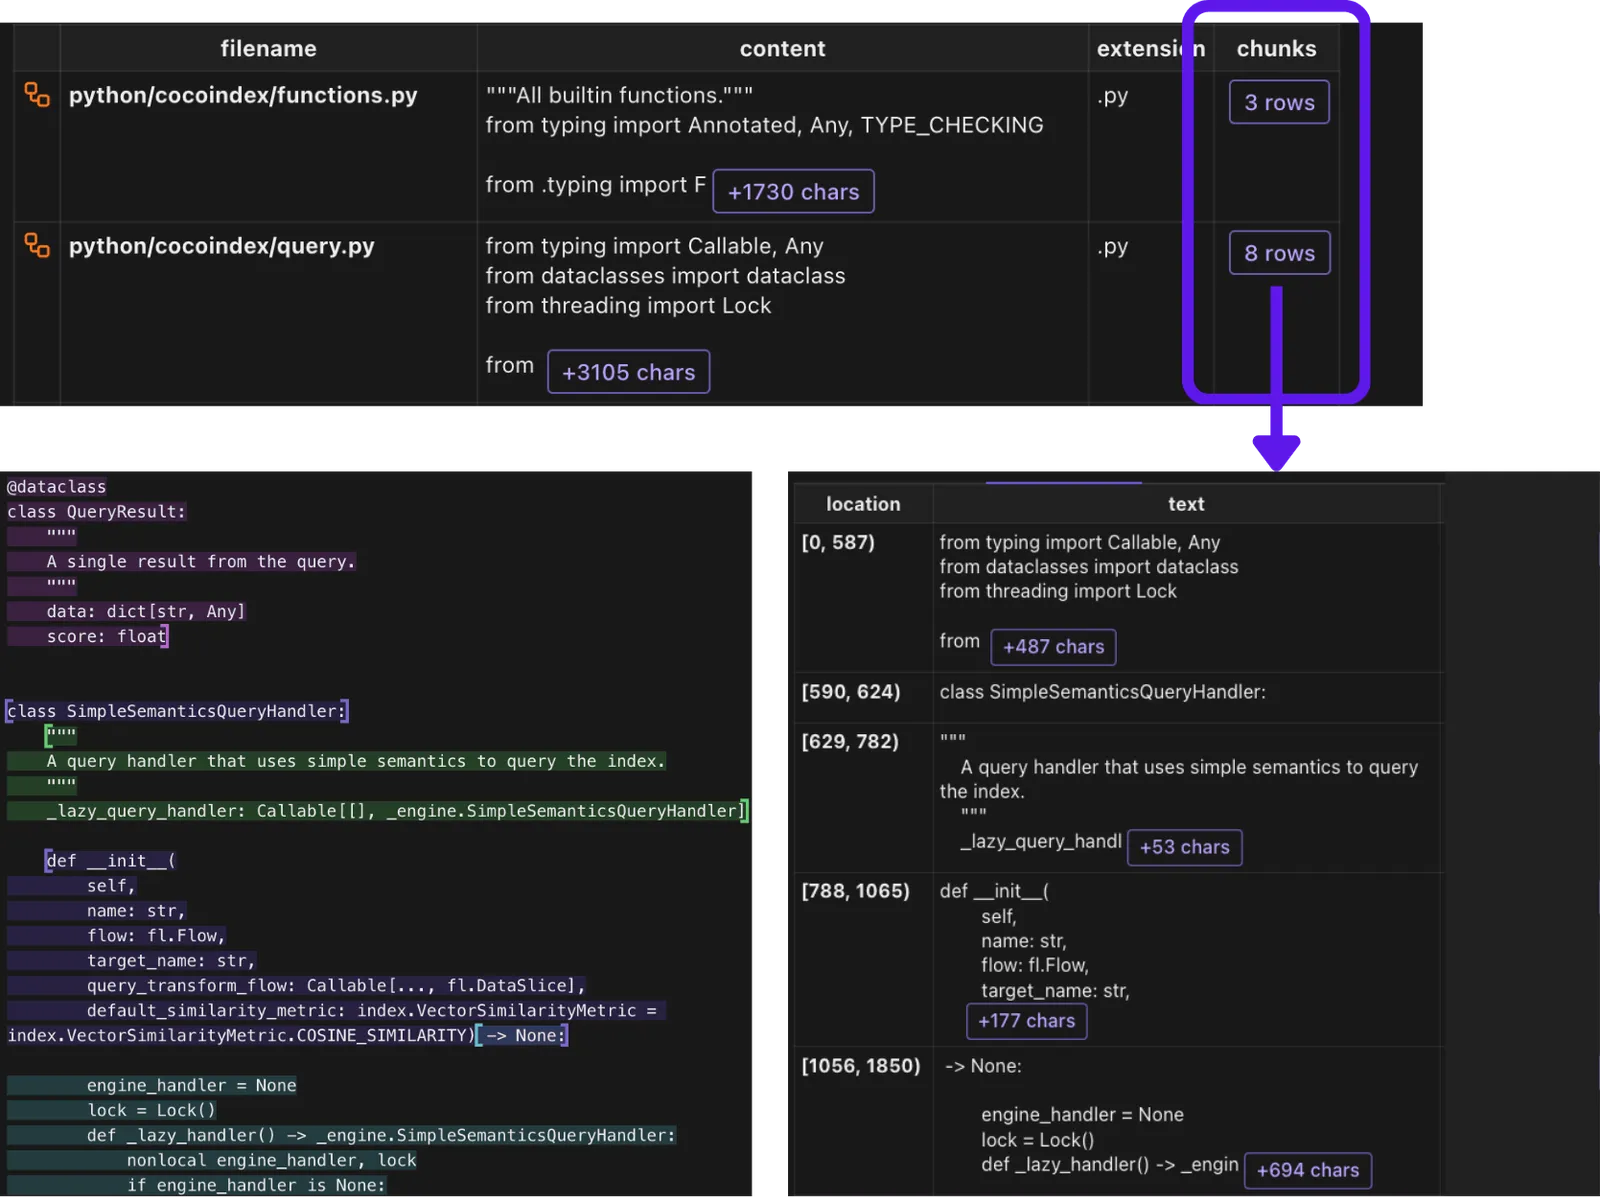
2.3 Embed the chunks
We use SentenceTransformerEmbed to embed the chunks.
See the functions documentation.
Thousands of models on Hugging Face work with it.
Pick the model that fits your code.
@cocoindex.transform_flow()
def code_to_embedding(text: cocoindex.DataSlice[str]) -> cocoindex.DataSlice[list[float]]:
    """
    Embed the text using a SentenceTransformer model.
    """
    return text.transform(
        cocoindex.functions.SentenceTransformerEmbed(
            model="sentence-transformers/all-MiniLM-L6-v2"))
Then for each chunk, embed it using the code_to_embedding function and collect the embeddings to the code_embeddings collector.
@cocoindex.transform_flow() adds an eval() method, so the same embedding logic runs in the indexing flow and on a query string at query time. We build a vector index and query against it;
the embedding computation needs to be consistent between indexing and querying. See the V0 documentation on transform flows.
with data_scope["files"].row() as file:
    with file["chunks"].row() as chunk:
        chunk["embedding"] = chunk["text"].call(code_to_embedding)
        code_embeddings.collect(filename=file["filename"], location=chunk["location"],
                                code=chunk["text"], embedding=chunk["embedding"])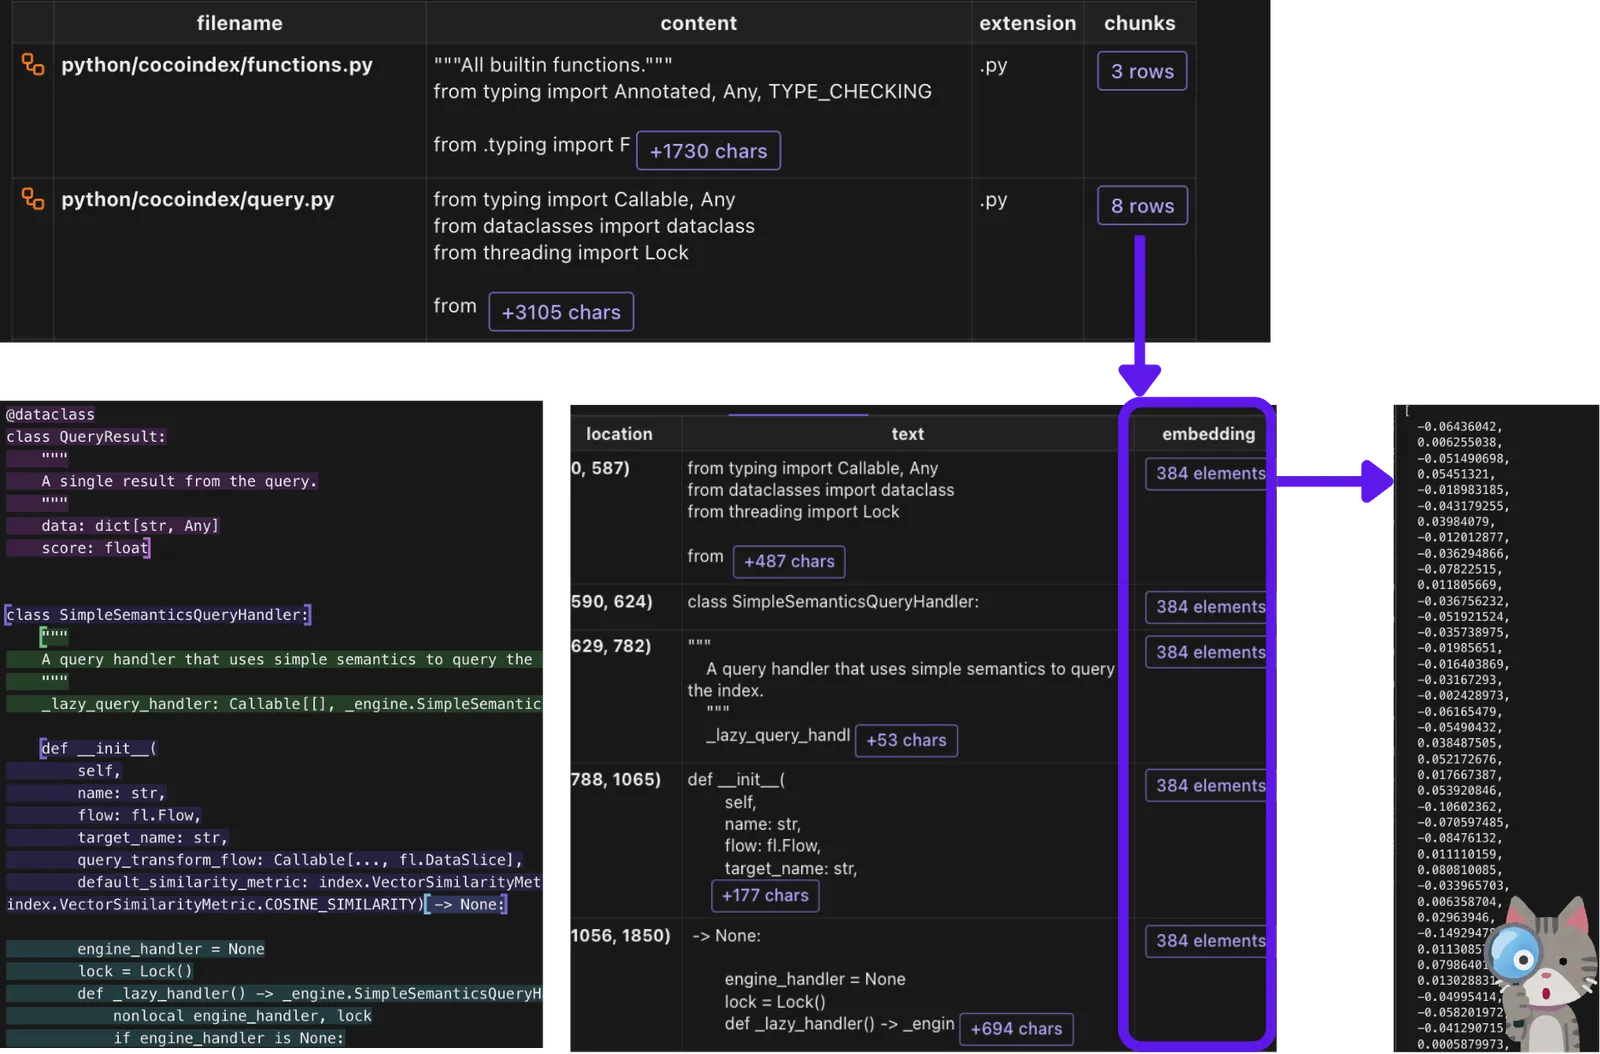
2.4 Collect the embeddings
Export the embeddings to a table.
code_embeddings.export(
    "code_embeddings",
    cocoindex.targets.Postgres(),
    primary_key_fields=["filename", "location"],
    vector_indexes=[
        cocoindex.VectorIndexDef(
            field_name="embedding",
            metric=cocoindex.VectorSimilarityMetric.COSINE_SIMILARITY,
        )
    ])
We use cosine similarity to measure the similarity between the query and the indexed data; see cosine similarity on Wikipedia.
3. Query the index
We match against user-provided text by a SQL query, reusing the embedding operation in the indexing flow.
def search(pool: ConnectionPool, query: str, top_k: int = 5):
    # Get the table name, for the export target in the code_embedding_flow above.
    table_name = cocoindex.utils.get_target_default_name(code_embedding_flow, "code_embeddings")
    # Evaluate the transform flow defined above with the input query, to get the embedding.
    query_vector = code_to_embedding.eval(query)
    # Run the query and get the results.
    with pool.connection() as conn:
        with conn.cursor() as cur:
            cur.execute(f"""
                SELECT filename, code, embedding <=> %s::vector AS distance
                FROM {table_name} ORDER BY distance LIMIT %s
            """, (query_vector, top_k))
            return [
                {"filename": row[0], "code": row[1], "score": 1.0 - row[2]}
                for row in cur.fetchall()
            ]
Define a main function to run the query in the terminal.
from dotenv import load_dotenv


def main():
    # Initialize the database connection pool.
    pool = ConnectionPool(os.getenv("COCOINDEX_DATABASE_URL"))
    # Run queries in a loop to demonstrate the query capabilities.
    while True:
        try:
            query = input("Enter search query (or Enter to quit): ")
            if query == '':
                break
            # Run the query function with the database connection pool and the query.
            results = search(pool, query)
            print("\nSearch results:")
            for result in results:
                print(f"[{result['score']:.3f}] {result['filename']}")
                print(f"    {result['code']}")
                print("---")
            print()
        except KeyboardInterrupt:
            break

if __name__ == "__main__":
    load_dotenv()
    cocoindex.init()
    main()
Set up and update the index
Run the following command to set up and update the index. Setup runs as part of update; confirm the prompt, or pass -f to skip it.
cocoindex update mainThe terminal shows the update progress.
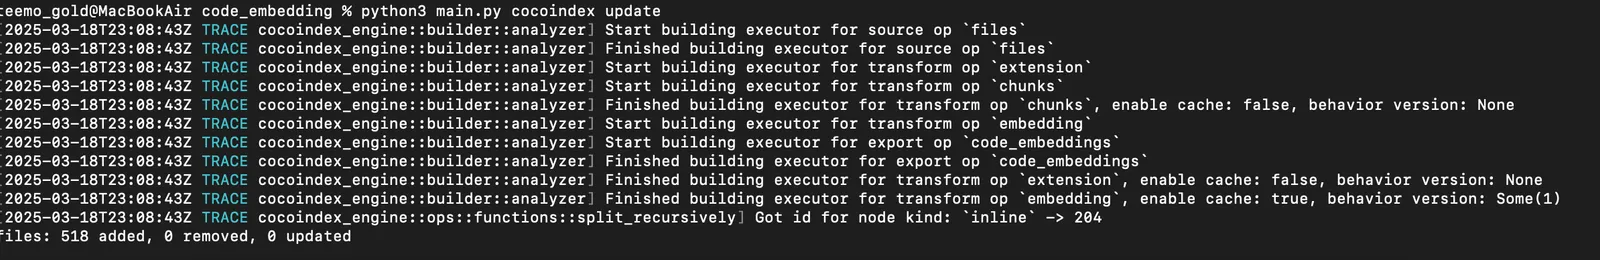
Read terminal output
Captured with an earlier CLI; today the command is cocoindex update main.
teemo_gold@MacBookAir code_embedding % python3 main.py cocoindex update
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Start building executor for source op `files`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Finished building executor for source op `files`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Start building executor for transform op `extension`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Start building executor for transform op `chunks`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Finished building executor for transform op `chunks`, enable cache: false, behavior version: None
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Start building executor for transform op `embedding`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Start building executor for export op `code_embeddings`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Finished building executor for export op `code_embeddings`
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Finished building executor for transform op `extension`, enable cache: false, behavior version: None
[2025-03-18T23:08:43Z TRACE cocoindex_engine::builder::analyzer] Finished building executor for transform op `embedding`, enable cache: true, behavior version: Some(1)
[2025-03-18T23:08:43Z TRACE cocoindex_engine::ops::functions::split_recursively] Got id for node kind: `inline` -> 204
files: 518 added, 0 removed, 0 updated
Test the query
At this point, you can develop your RAG runtime against the data. To test the index, run:
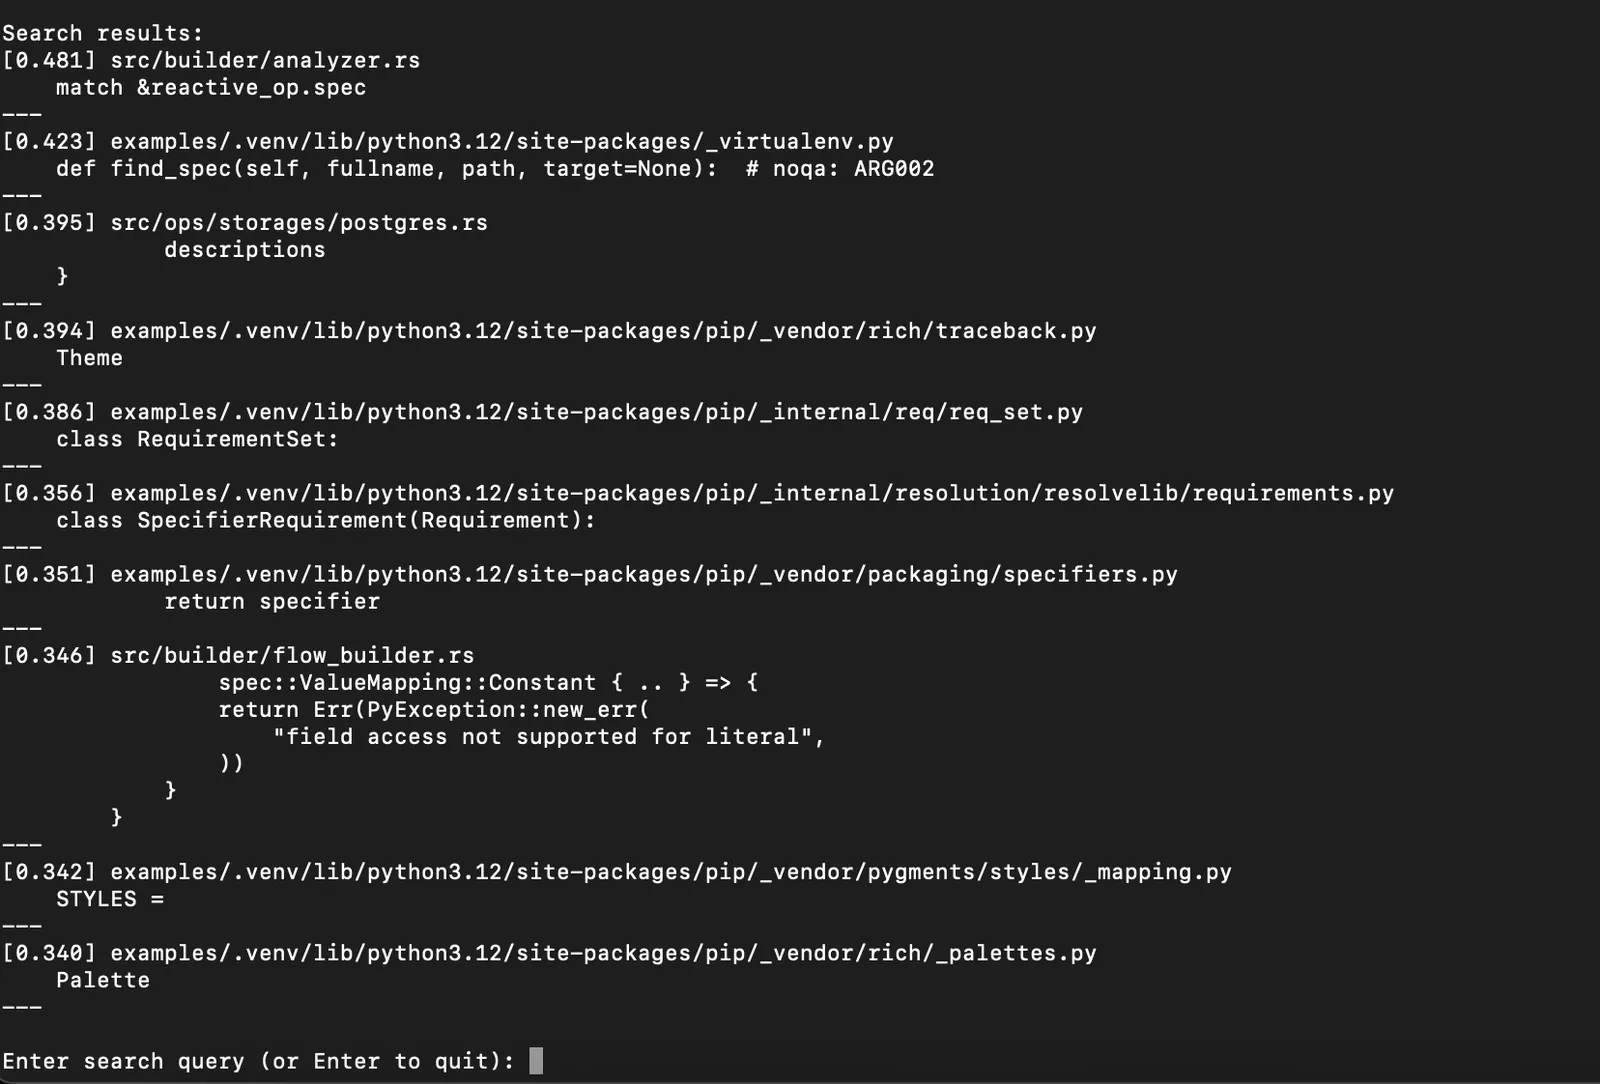
python main.pyWhen you see the prompt, enter a search query, for example spec.
You can find the search results in the terminal.
Read terminal output
Search results:
[0.481] src/builder/analyzer.rs
    match &reactive_op.spec
---
[0.423] examples/.venv/lib/python3.12/site-packages/_virtualenv.py
    def find_spec(self, fullname, path, target=None):  # noqa: ARG002
---
[0.395] src/ops/storages/postgres.rs
            descriptions
    }
---
[0.394] examples/.venv/lib/python3.12/site-packages/pip/_vendor/rich/traceback.py
    Theme
---
[0.386] examples/.venv/lib/python3.12/site-packages/pip/_internal/req/req_set.py
    class RequirementSet:
---
[0.356] examples/.venv/lib/python3.12/site-packages/pip/_internal/resolution/resolvelib/requirements.py
    class SpecifierRequirement(Requirement):
---
[0.351] examples/.venv/lib/python3.12/site-packages/pip/_vendor/packaging/specifiers.py
            return specifier
---
[0.346] src/builder/flow_builder.rs
                spec::ValueMapping::Constant { .. } => {
                return Err(PyException::new_err(
                    "field access not supported for literal",
                ))
            }
        }
---
[0.342] examples/.venv/lib/python3.12/site-packages/pip/_vendor/pygments/styles/_mapping.py
    STYLES =
---
[0.340] examples/.venv/lib/python3.12/site-packages/pip/_vendor/rich/_palettes.py
    Palette
---

Enter search query (or Enter to quit):
Each result shows the score (cosine similarity), the filename, and the matched chunk.
Source
Browse the CocoIndex source on GitHub. For the same pipeline on the CocoIndex V1 API, with incremental updates explained chunk by chunk, read Codebase indexing for AI agents with CocoIndex.
Frequently asked questions
How do I index a codebase for RAG with CocoIndex?
You build a short indexing flow: add the codebase as a LocalFile source, extract each file's extension to detect its language, split the code into semantic chunks with Tree-sitter, embed each chunk, and export the embeddings to a vector index in Postgres. The indexing path is only about 50 lines of Python, and you query it by reusing the same embedding function.
See Define indexing flow.
Why use Tree-sitter for chunking code instead of fixed line windows?
CocoIndex uses Tree-sitter to chunk code based on the actual syntax structure rather than arbitrary line breaks. Chunks that follow the syntax give retrieval whole functions and blocks to return, instead of fragments. Tree-sitter is a parser generator and incremental parsing library available in Rust.
See Tree-sitter.
Which programming languages can CocoIndex chunk with Tree-sitter?
Chunking uses the SplitRecursively function, which is integrated with Tree-sitter; you pass the language via the language parameter (here derived from the file extension). Supported languages include Python, Rust, JavaScript, TypeScript, Java and C++. If the language is unspecified or unsupported, the content is treated as plain text.
How do I choose an embedding model for code search in CocoIndex?
The example embeds chunks with SentenceTransformerEmbed using the sentence-transformers/all-MiniLM-L6-v2 model, but you can pick any of the 12k models supported by Hugging Face sentence-transformers. The embedding is wrapped in a @cocoindex.transform_flow() so the exact same computation is shared between the indexing path and the query path.
See Embed the chunks.
Why does the embedding need to be the same for indexing and querying?
You build a vector index at indexing time and query against it at search time, so the embedding computation must be consistent between the two; otherwise the query vector and the indexed vectors are not comparable. CocoIndex handles this by sharing the embedding logic through @cocoindex.transform_flow(), which the query path reuses via code_to_embedding.eval(query).
See Embed the chunks and Query the index.
How does CocoIndex keep a code index up to date in near real-time?
CocoIndex reprocesses only the files that changed. With a source that pushes change notifications, such as a code editor, the index follows edits as they happen. Postgres tracks the data lineage this needs.
See Prerequisites.
How do I query the code embeddings index?
You match user text against the index with a SQL query that reuses the indexing flow's embedding operation to turn the query into a vector, then orders results by pgvector's cosine distance (embedding <=> %s::vector) and returns the top-k. Each result carries a cosine similarity score, the filename, and the matched chunk. Run python main.py and type a query at the prompt.
See Query the index and Test the query.
About the author

Posts from the CocoIndex team — product launches, release notes, and announcements.
Build fresh context for your agents.
CocoIndex keeps derived data in sync with its sources. Only what changed re-runs.